About me (CV)
I am currently a Ph.D. student at the University of Hong Kong, under the supervision of Professor Yi Ma. I was graduated as a Master student from MCG GROUP at Nanjing University, supervised by Prof. Limin Wang. And I also obtained the B.Sc degree from Nanjing University in 2021, where I was fortunate to cross paths with my mentor, setting the course for my academic journey.
My academic pursuits are centered on computer vision and graphics. Currently I am focused on Generative Models and Accelerating Diffuison Models. I have a consistent interest on Vision-Language Foundation Models.
Research
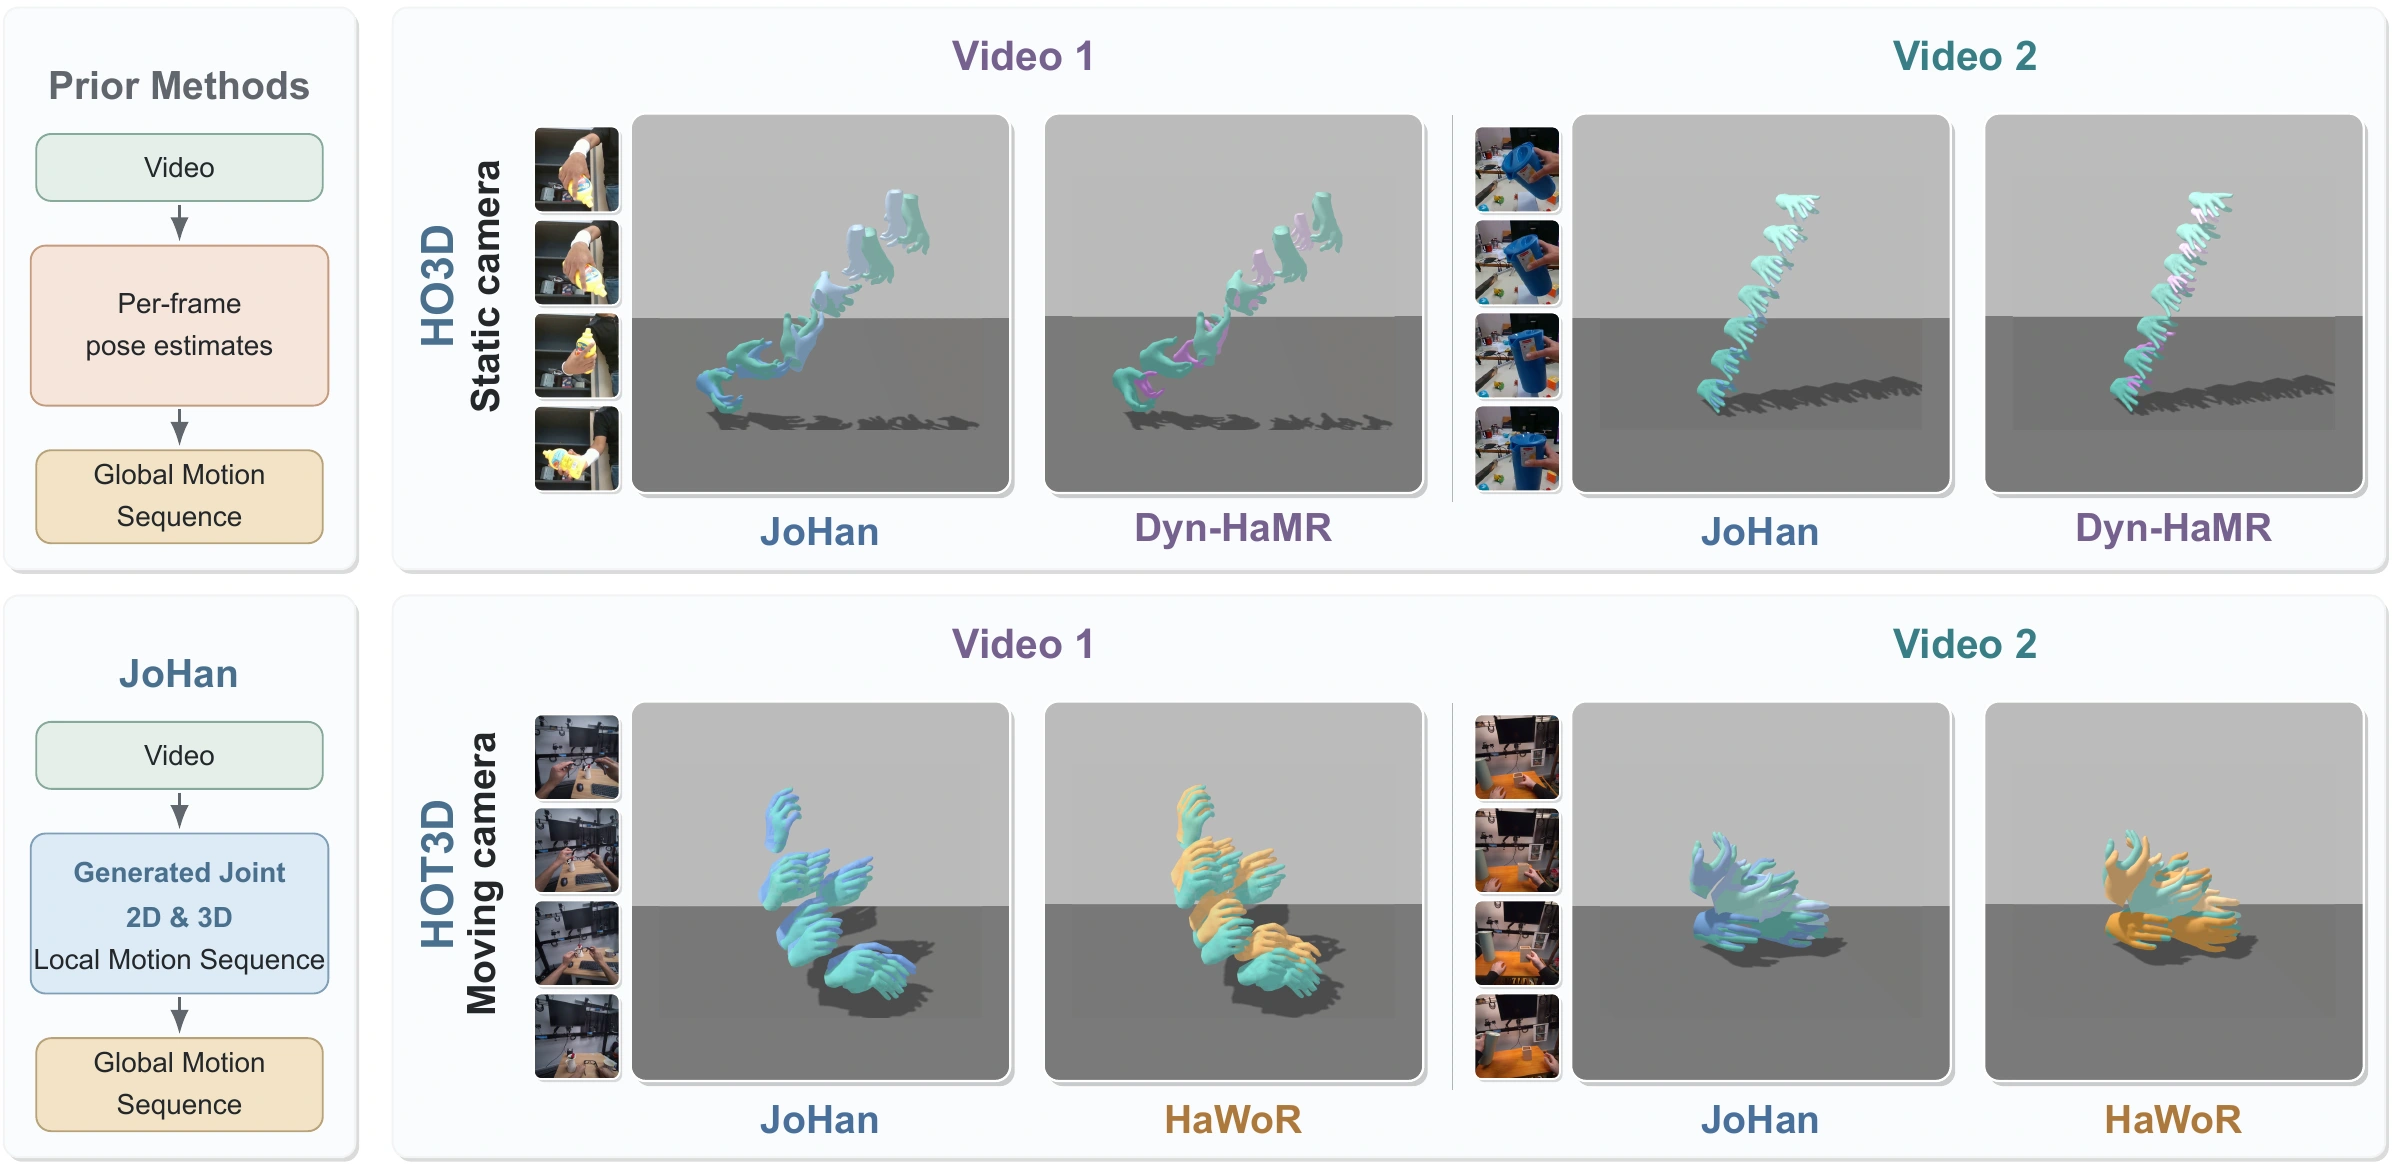
Video-Conditioned Generative Joint 2D–3D Hand Motion Recovery
Chen Xu, Yunqi Li, Binbin Huang, Brent Yi, Shenghua Gao, Yi MaarXiv, 2026
arXiv / code / project
JoHan jointly generates aligned 2D and 3D local hand motion directly from video, followed by geometric recovery of global orientation and translation.

Accelerating Image Generation with Sub-Path Linear Approximation Model
Chen Xu*, Tianhui Song*, Weixin Feng, Xubin Li, Tiezheng Ge, Bo Zheng, Limin WangECCV Oral, 2024
arXiv / code / project
Sub-path Linear Approximation Models (SPLAM) give a continous and progressive error estimation for separated PF-ODE sub-paths and generate images with high quality and smaller cumulative errors.
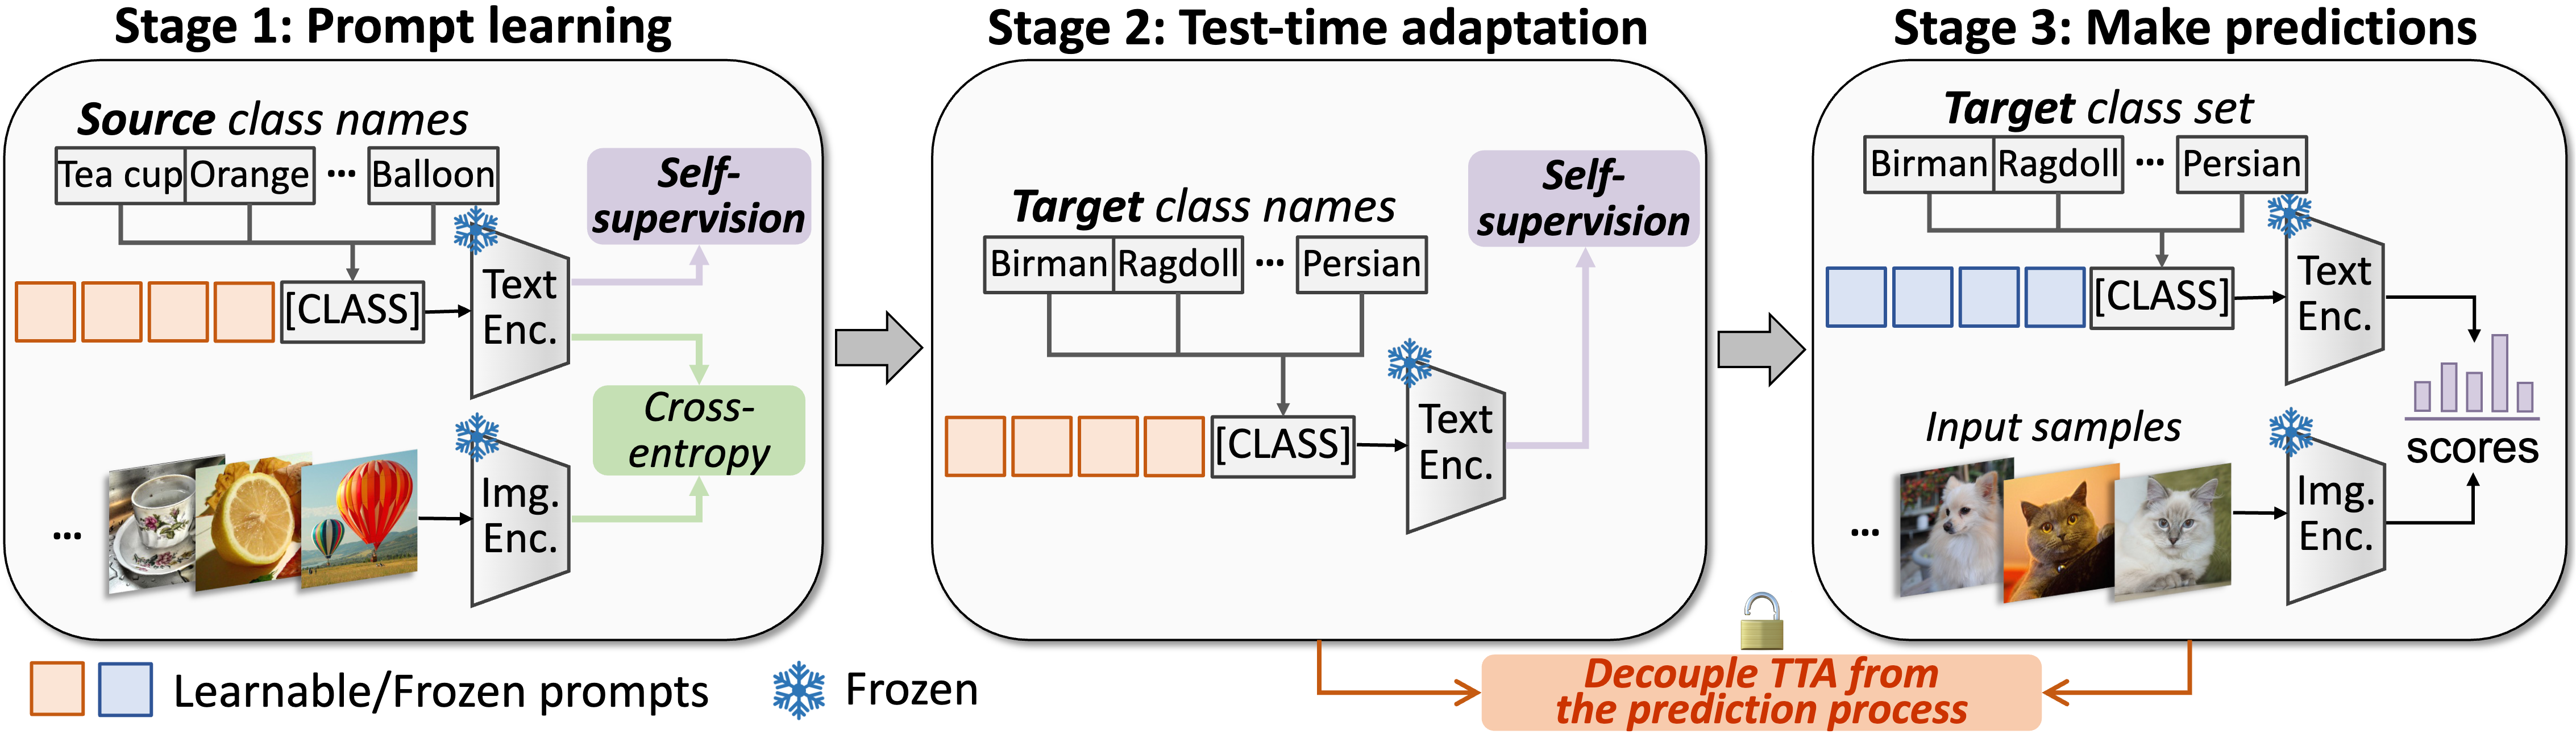
Efficient Test-Time Prompt Tuning for Vision-Language Models
Yuhan Zhu, Guozhen Zhang, Chen Xu, Haocheng Shen, Xiaoxin Chen, Gangshan Wu, Limin WangArxiv , 2024
arXiv
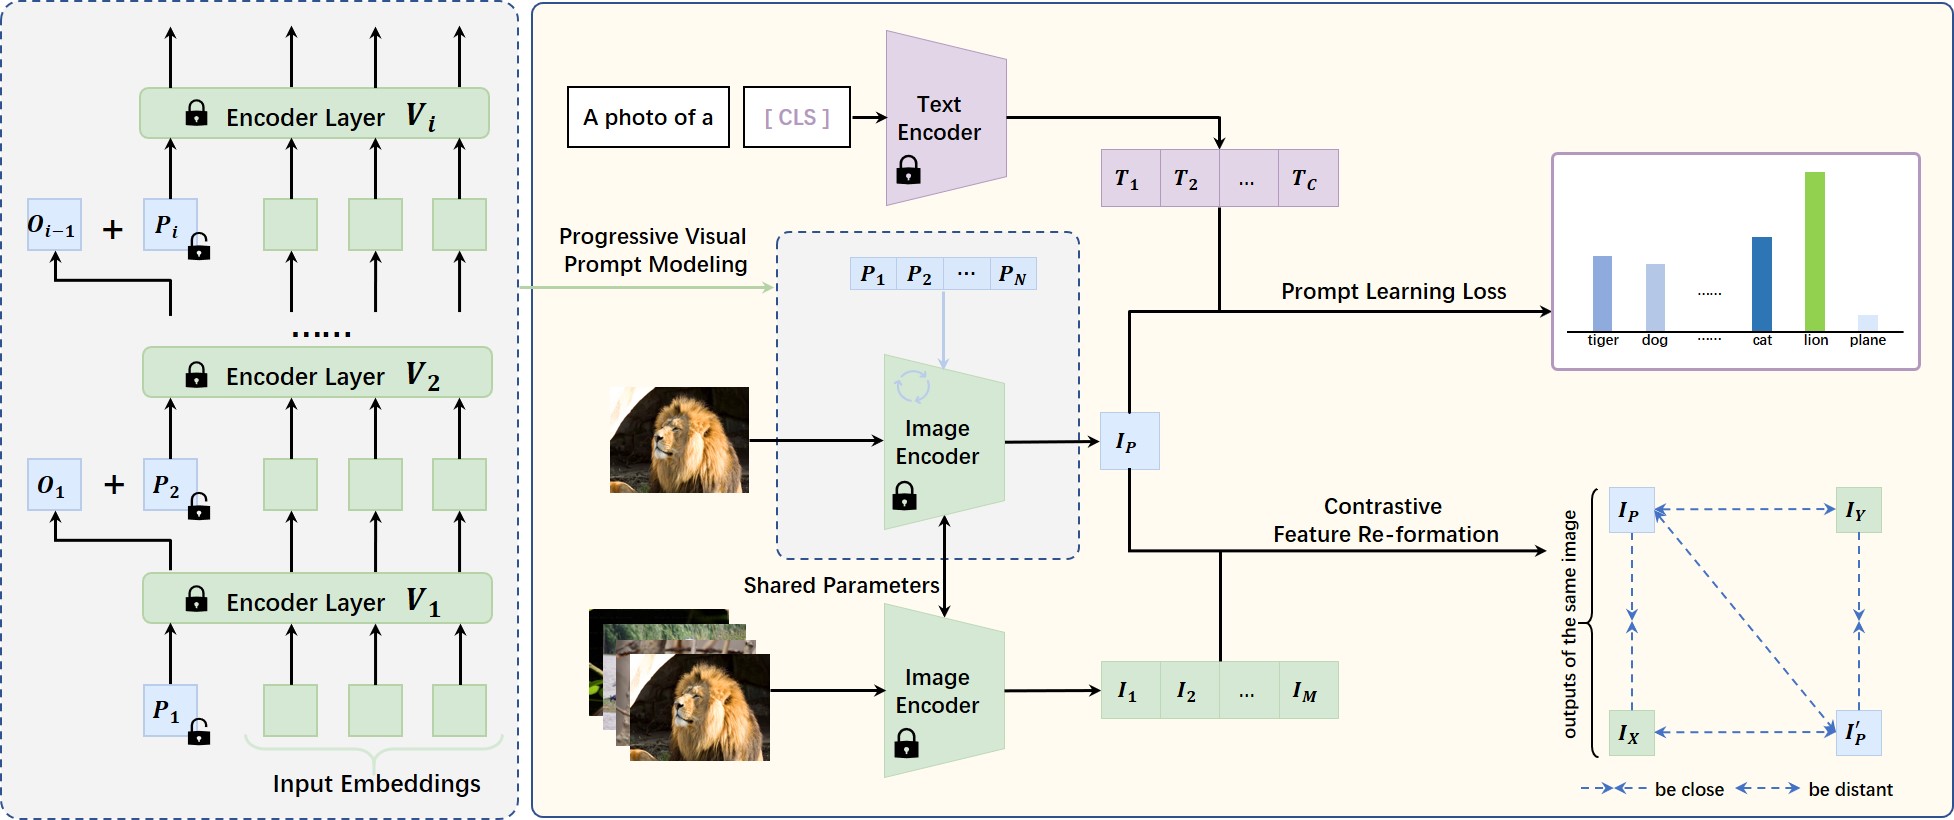
Progressive Visual Prompt Learning with Contrastive Feature Re-formation
Chen Xu, Yuhan Zhu, Haocheng Shen, Boheng Chen, Yixuan Liao, Xiaoxin Chen, Gangshan Wu, Limin WangIJCV, 2024
arXiv / code
We present Progressive Visual Prompt Learning with Contrastive Feature Re-formation (ProVP-Ref), a novel visual prompt learning architecture for the efficient transfer learning of Vision-language Models.
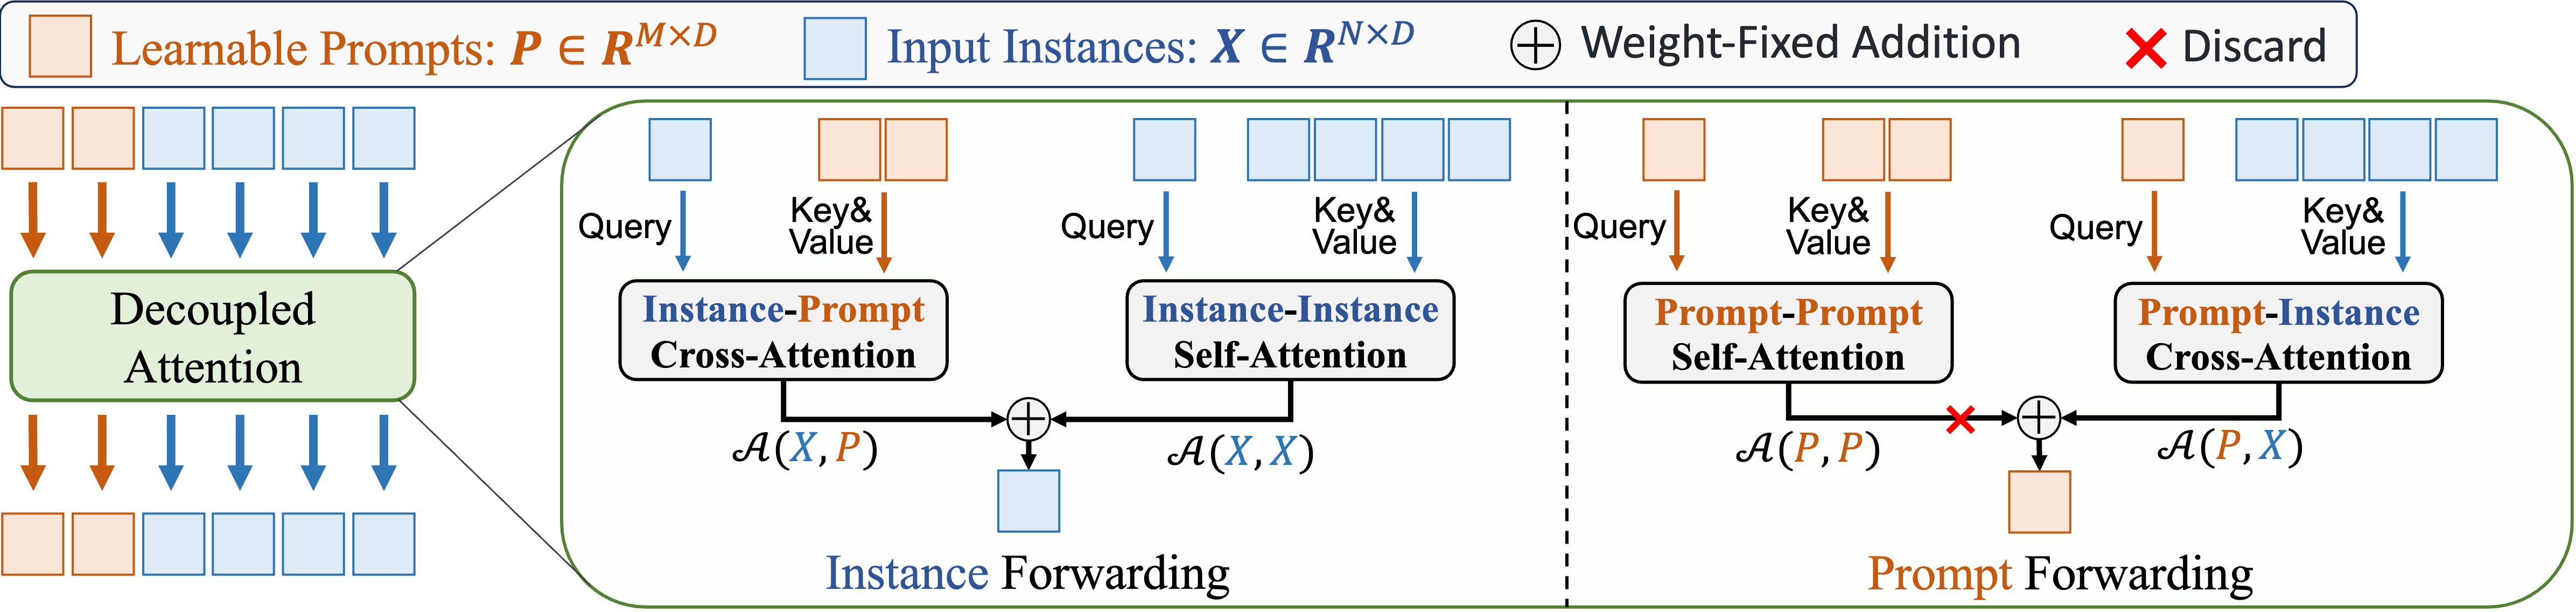
DPL: Decoupled Prompt Learning for Vision-Language Models
Chen Xu*, Yuhan Zhu*, Haocheng Shen, Boheng Chen, Yixuan Liao, Xiaoxin Chen, Gangshan Wu, Limin WangArxiv, 2024
arXiv
We present Decoupled Prompt Learning (DPL), a general prompt learning architecture which decouples the attention calculations between the input instance and learnable prompts, and then recombines them to establish a more effective and effcient learning for Vision-language Models with better generalization ablity.